
Training data, evaluation and live review for
From the first dataset to live production, we run every stage of your model's data: collection, labelling, evaluation and human review of live output.
Live review response, held 24/7 for six months inside a client’s production pipeline.
Client A · construction finance
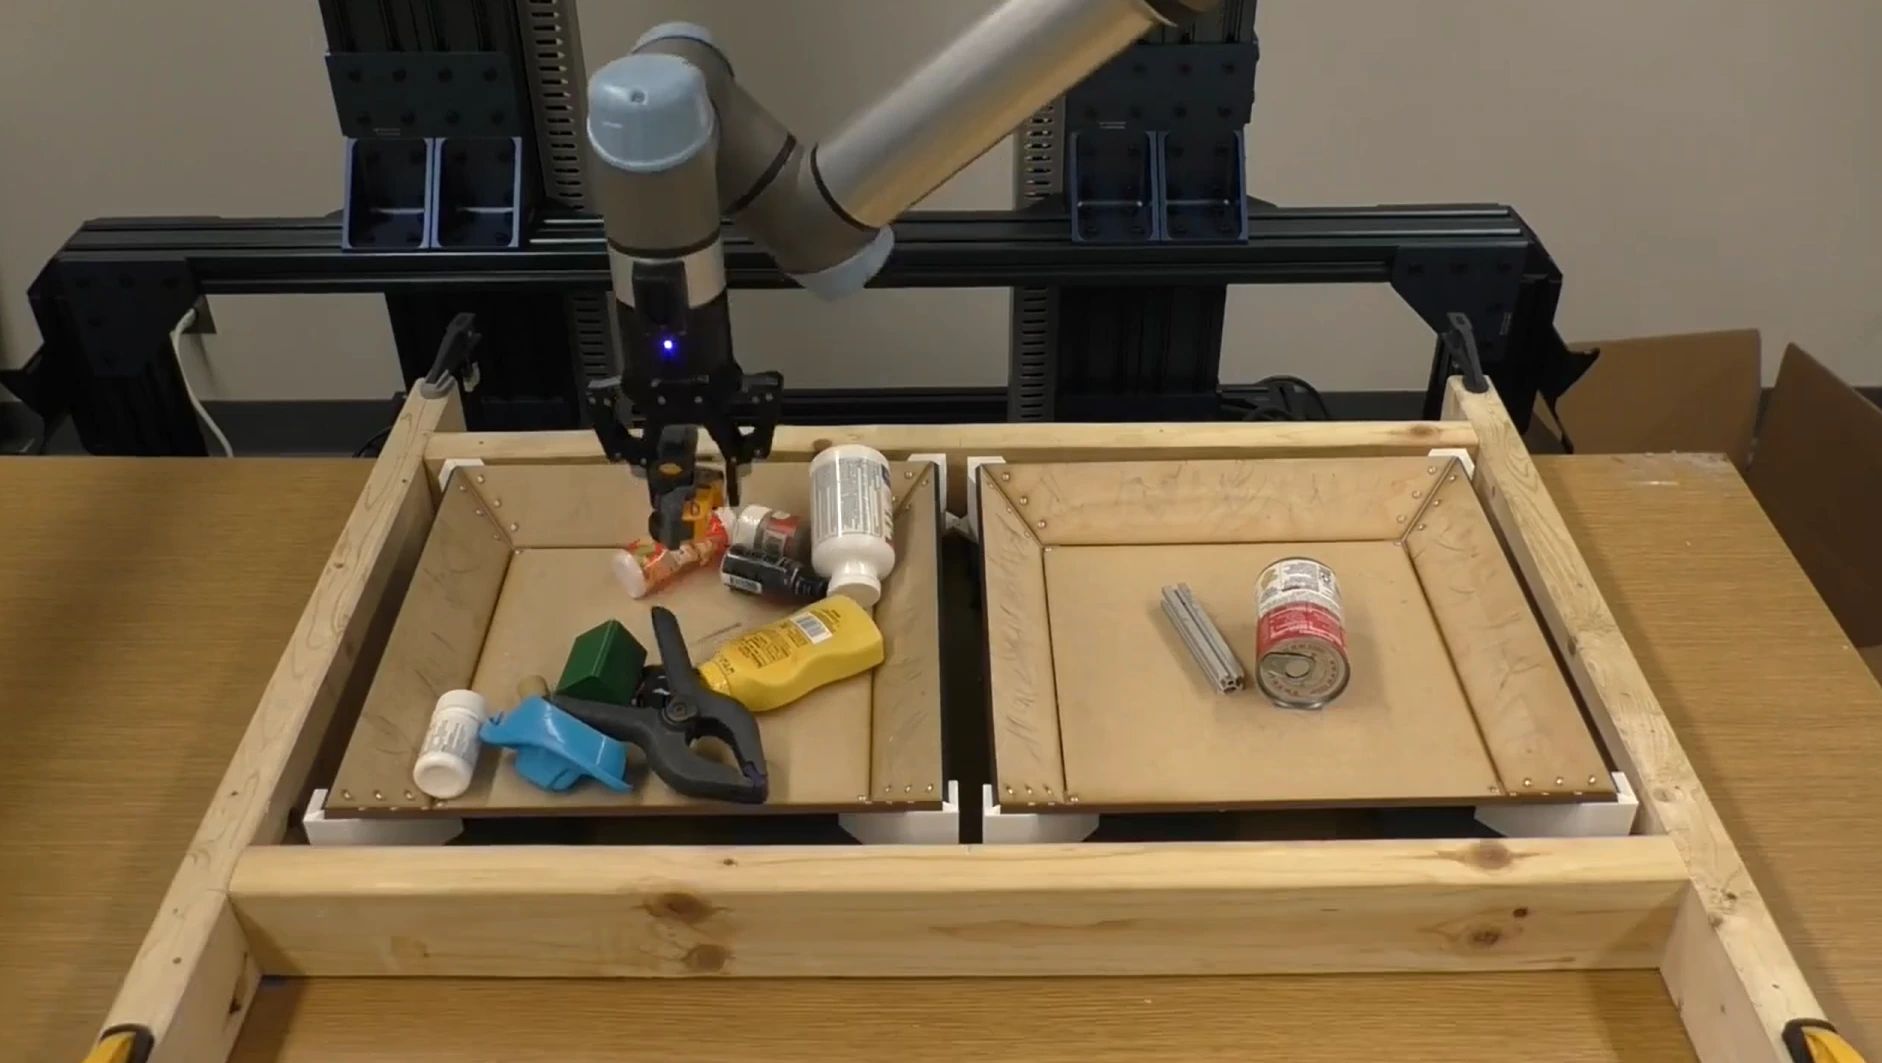
Robot videos described a week, each finished within five times its own length.
Client B · robotics
Images labeled for autonomous navigation, with every file kept on EU servers.
Client C · mapping
QA accuracy held while daily volume grew twelve times in five weeks.
Client D · retail food
Every stage of the model, run end to end.
Collect, annotate, evaluate and review live output on one schema, one set of guidelines and one quality record, so every fix flows back into the next round of training.
Data your model has never seen
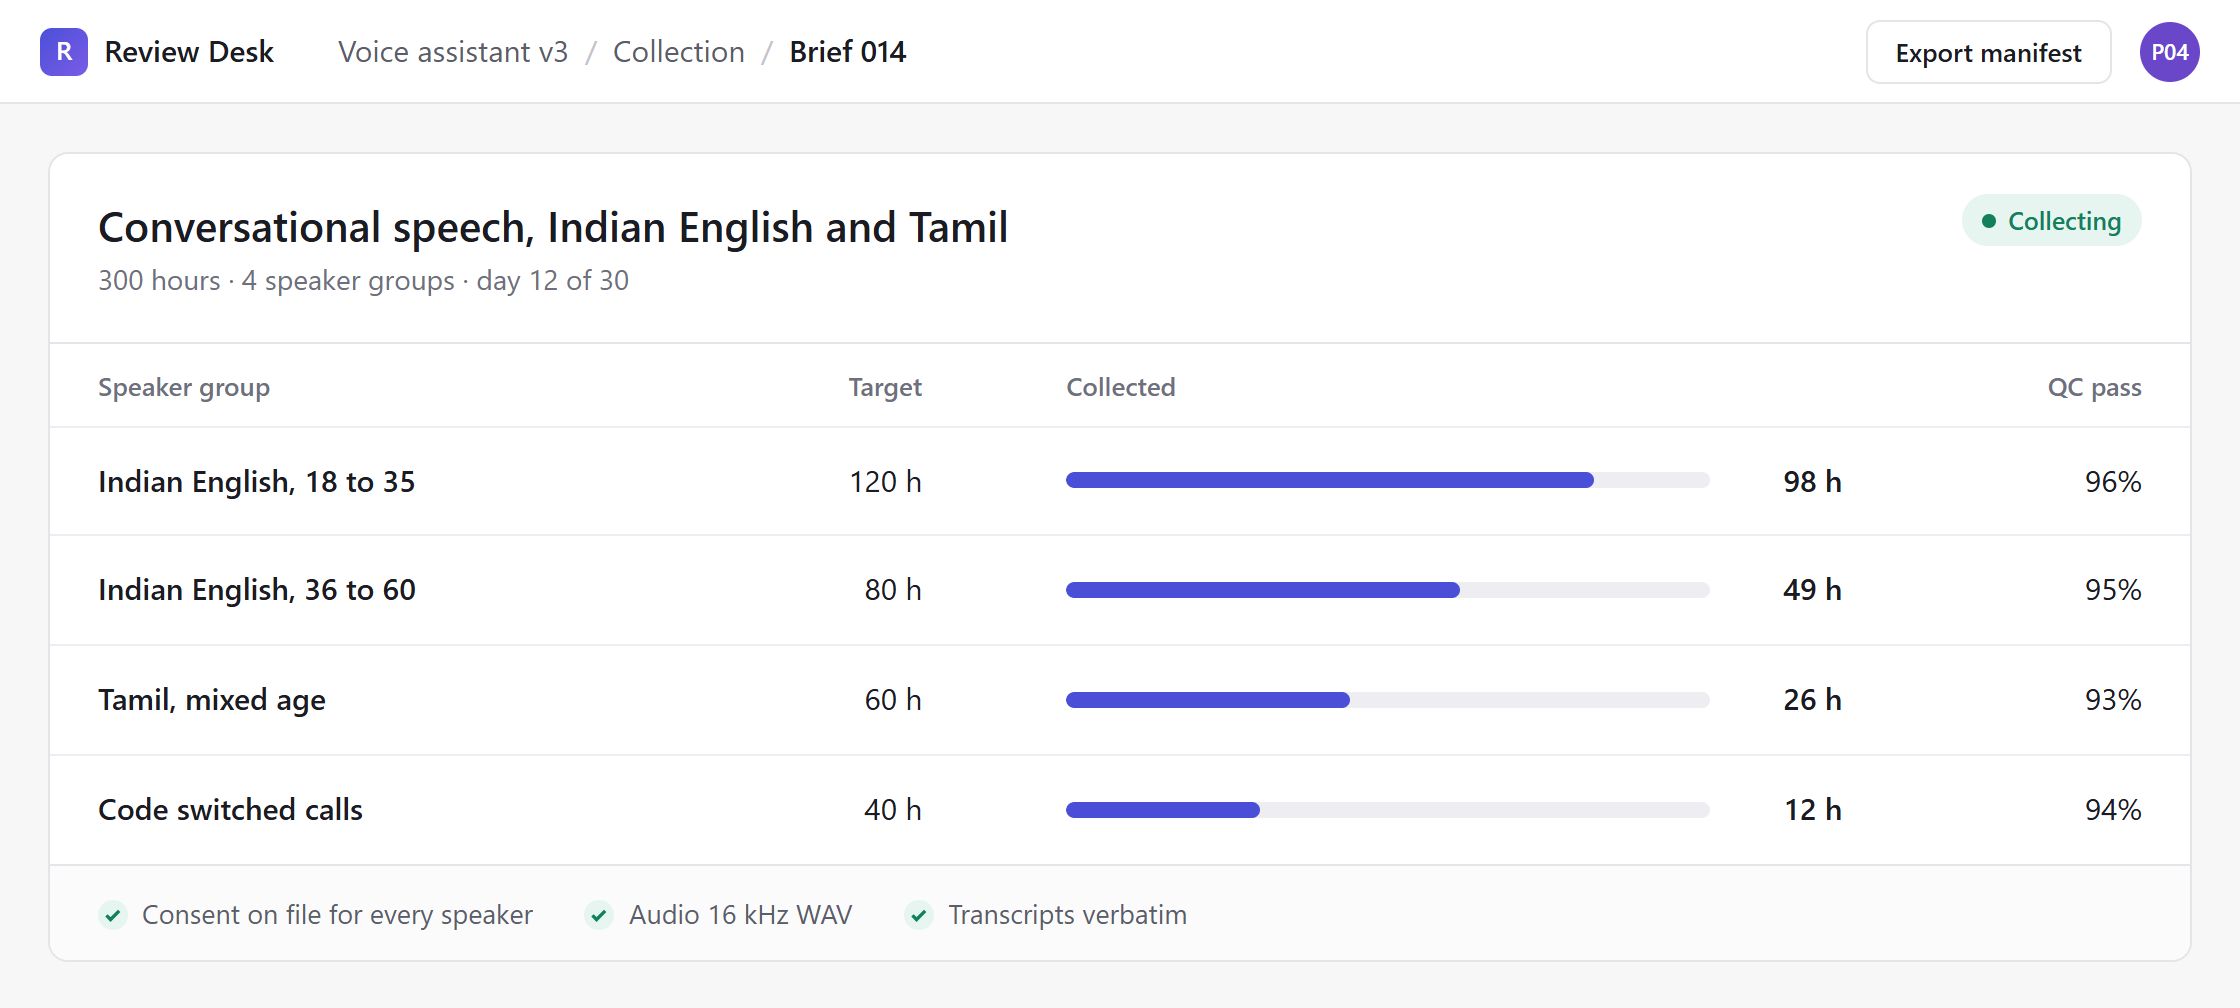
Speech, images, video and documents captured to a brief, with consent on file and quotas tracked by group.
Collect services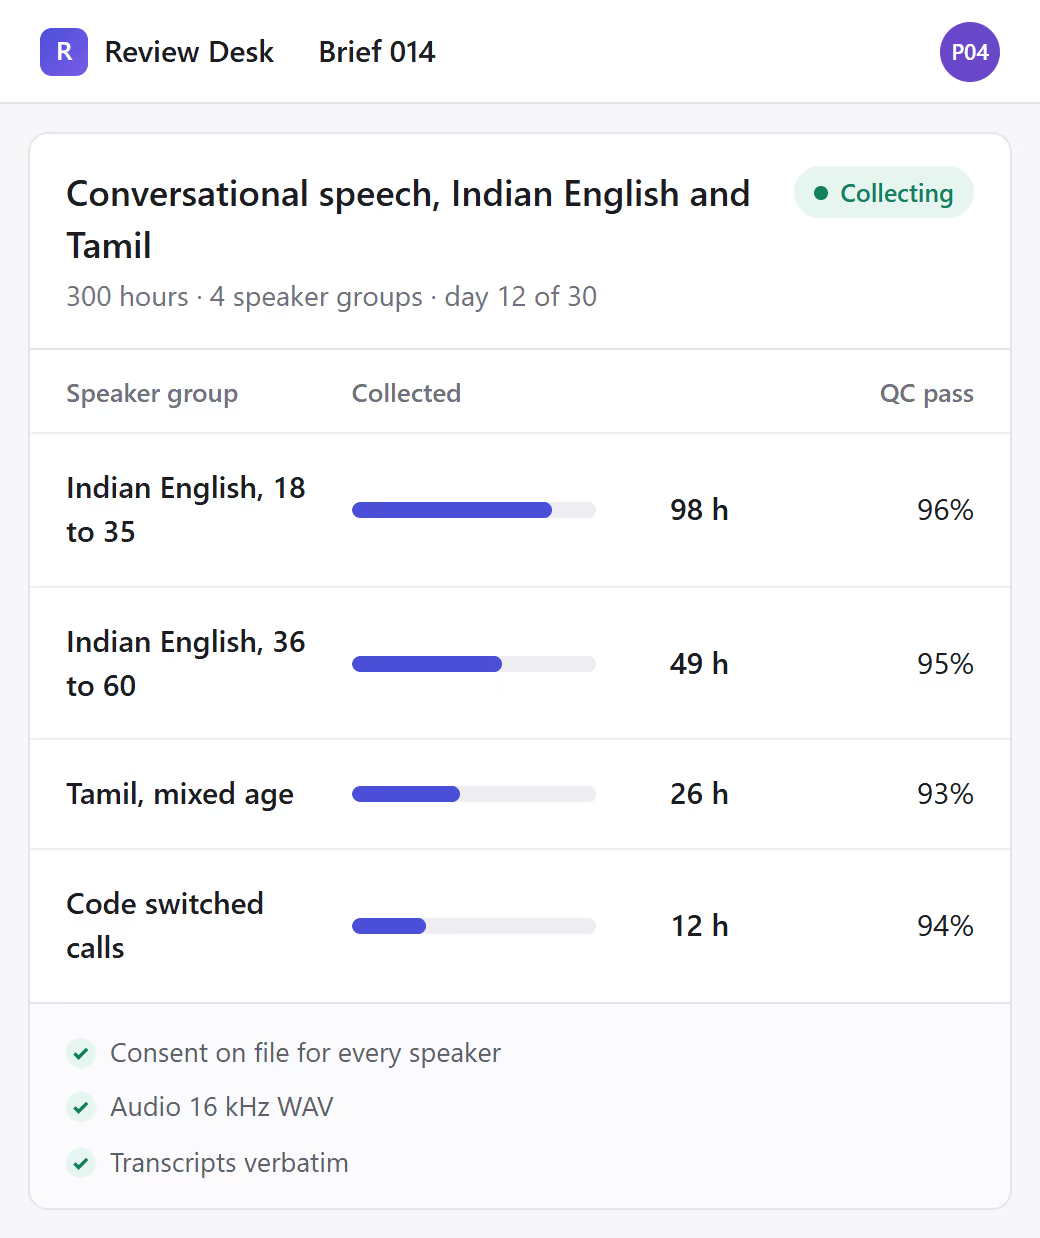
Labels built to your schema
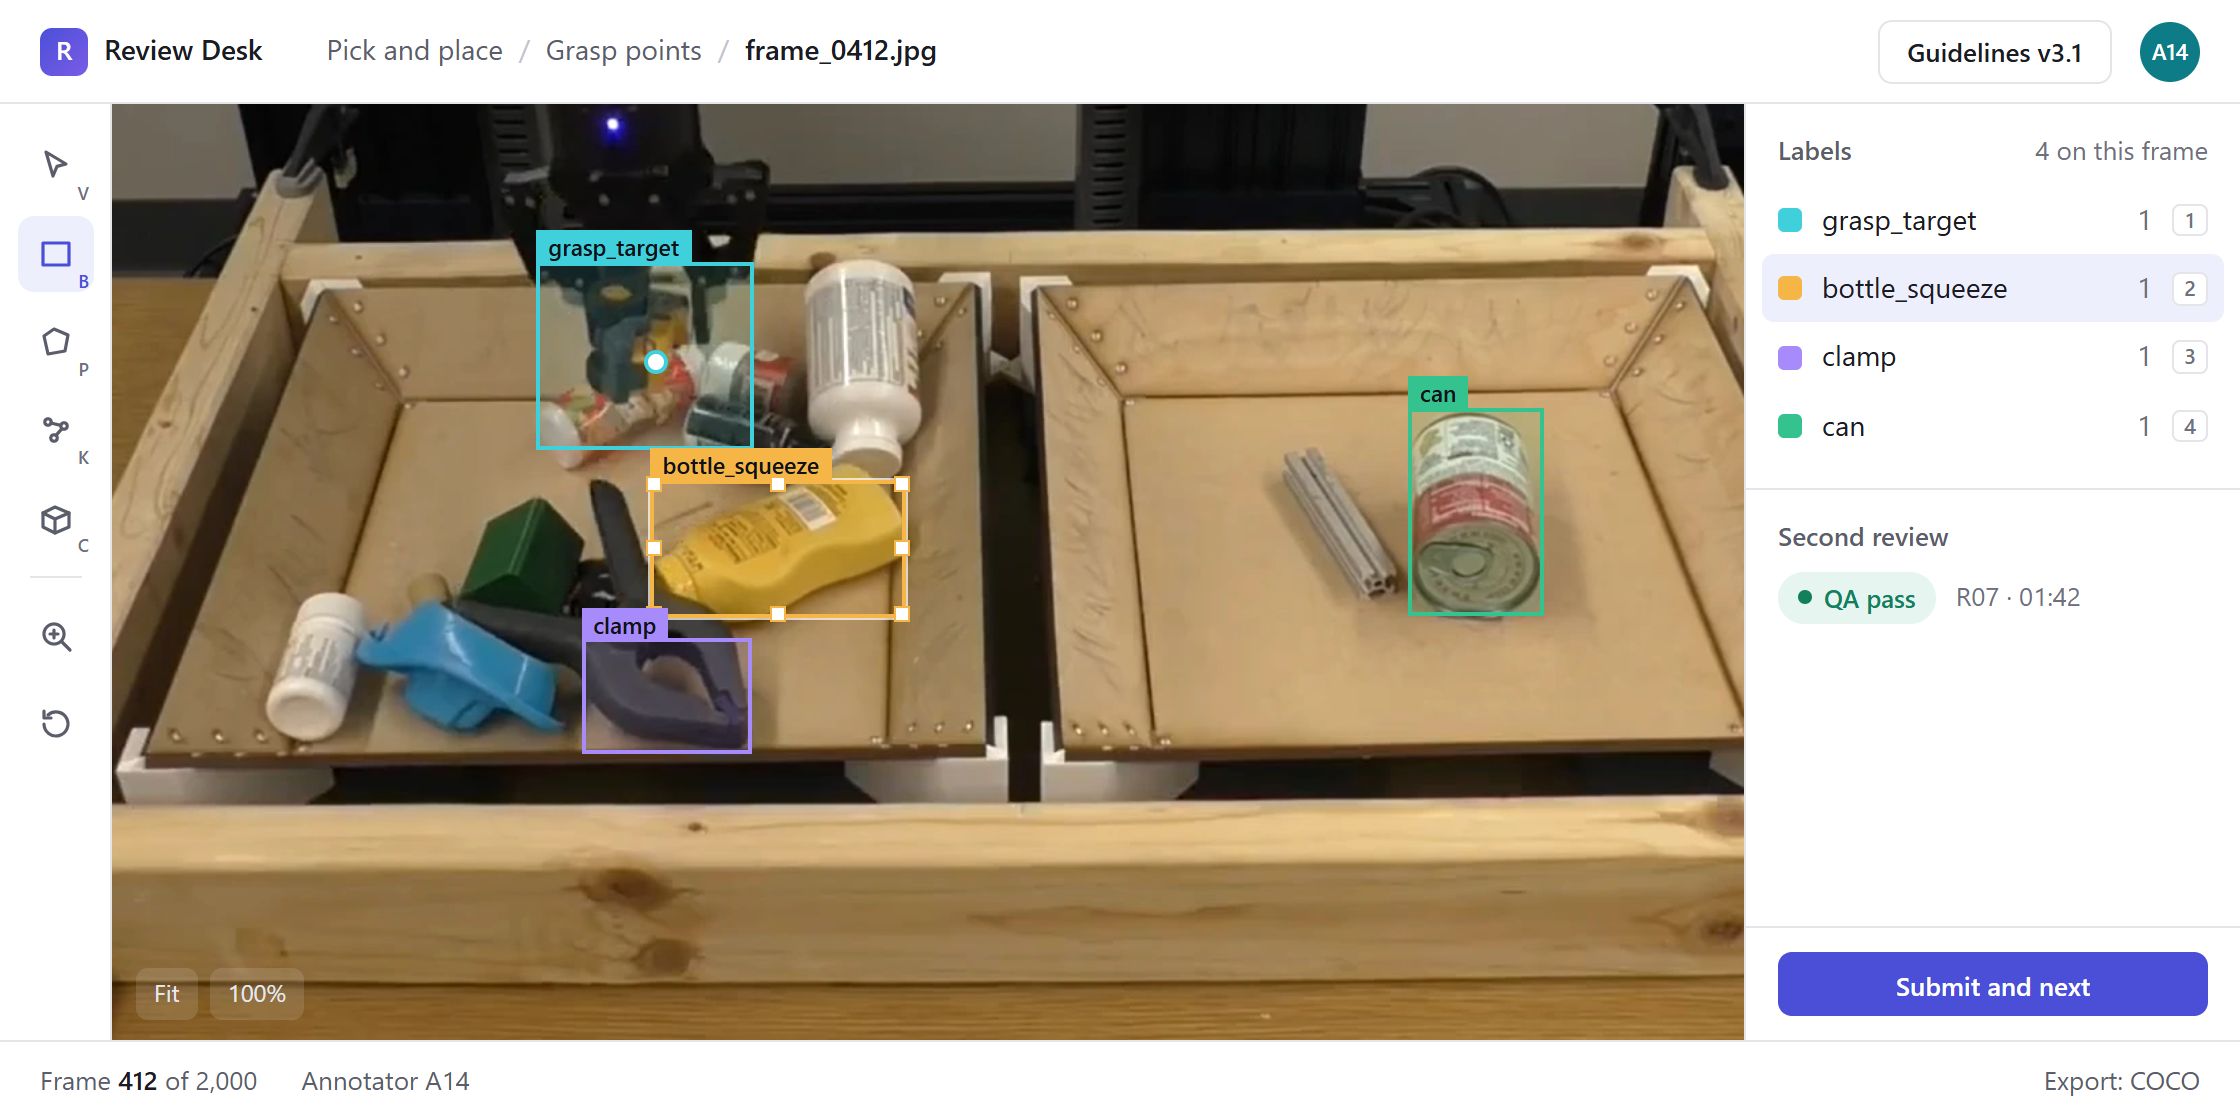
Boxes, polygons, cuboids, keypoints, transcripts and document fields, in your tool or ours, checked by a second reviewer.
Annotate services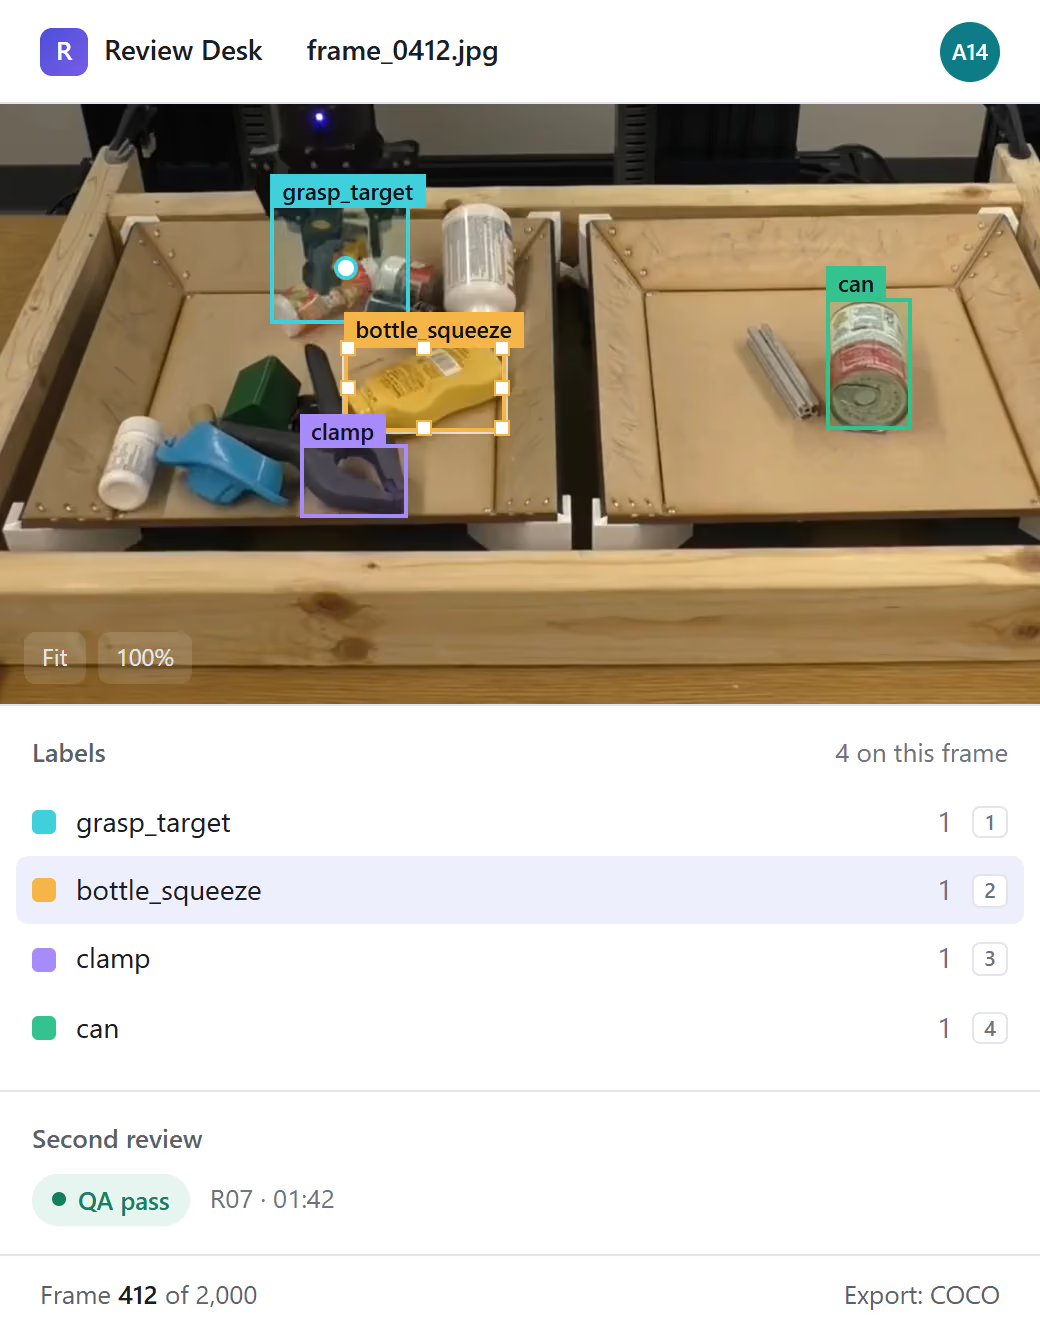
Find where the model fails
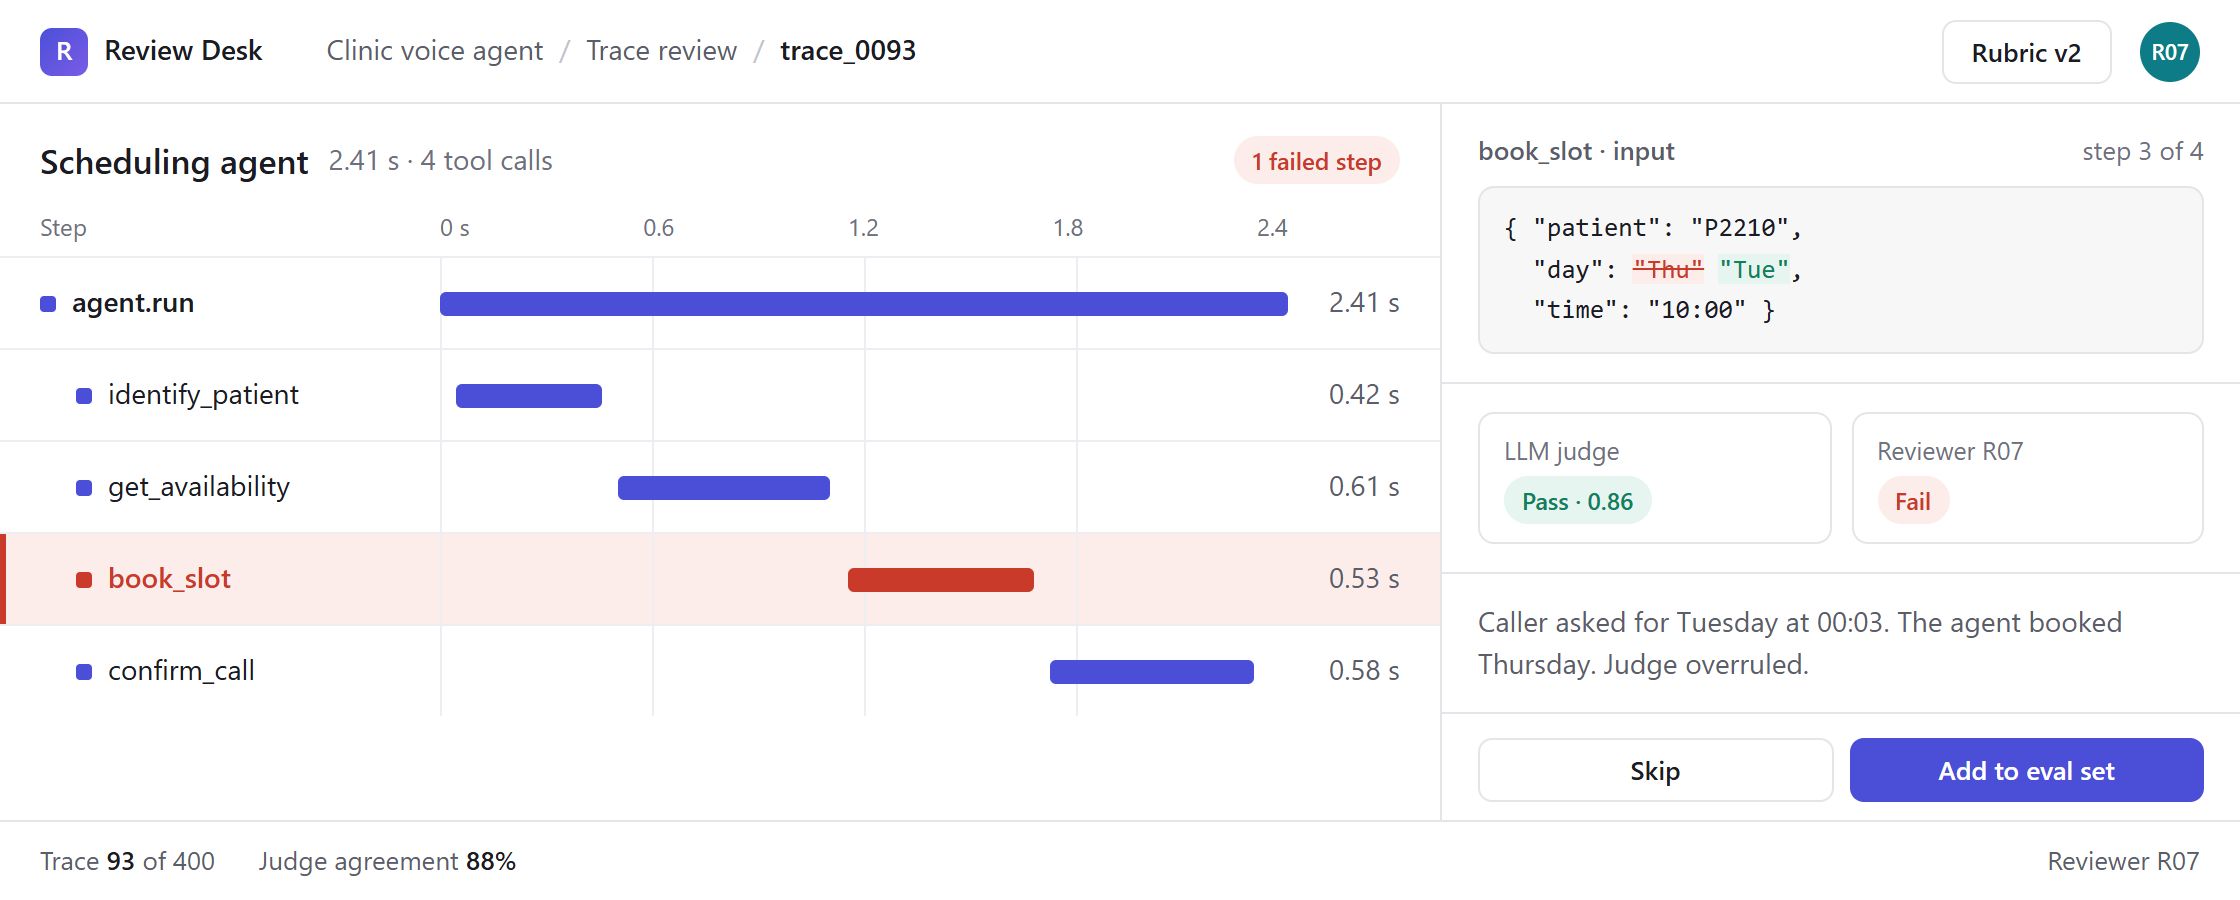
Agent traces scored step by step, LLM answers ranked against a rubric, and automated judges checked by people.
Evaluate and align services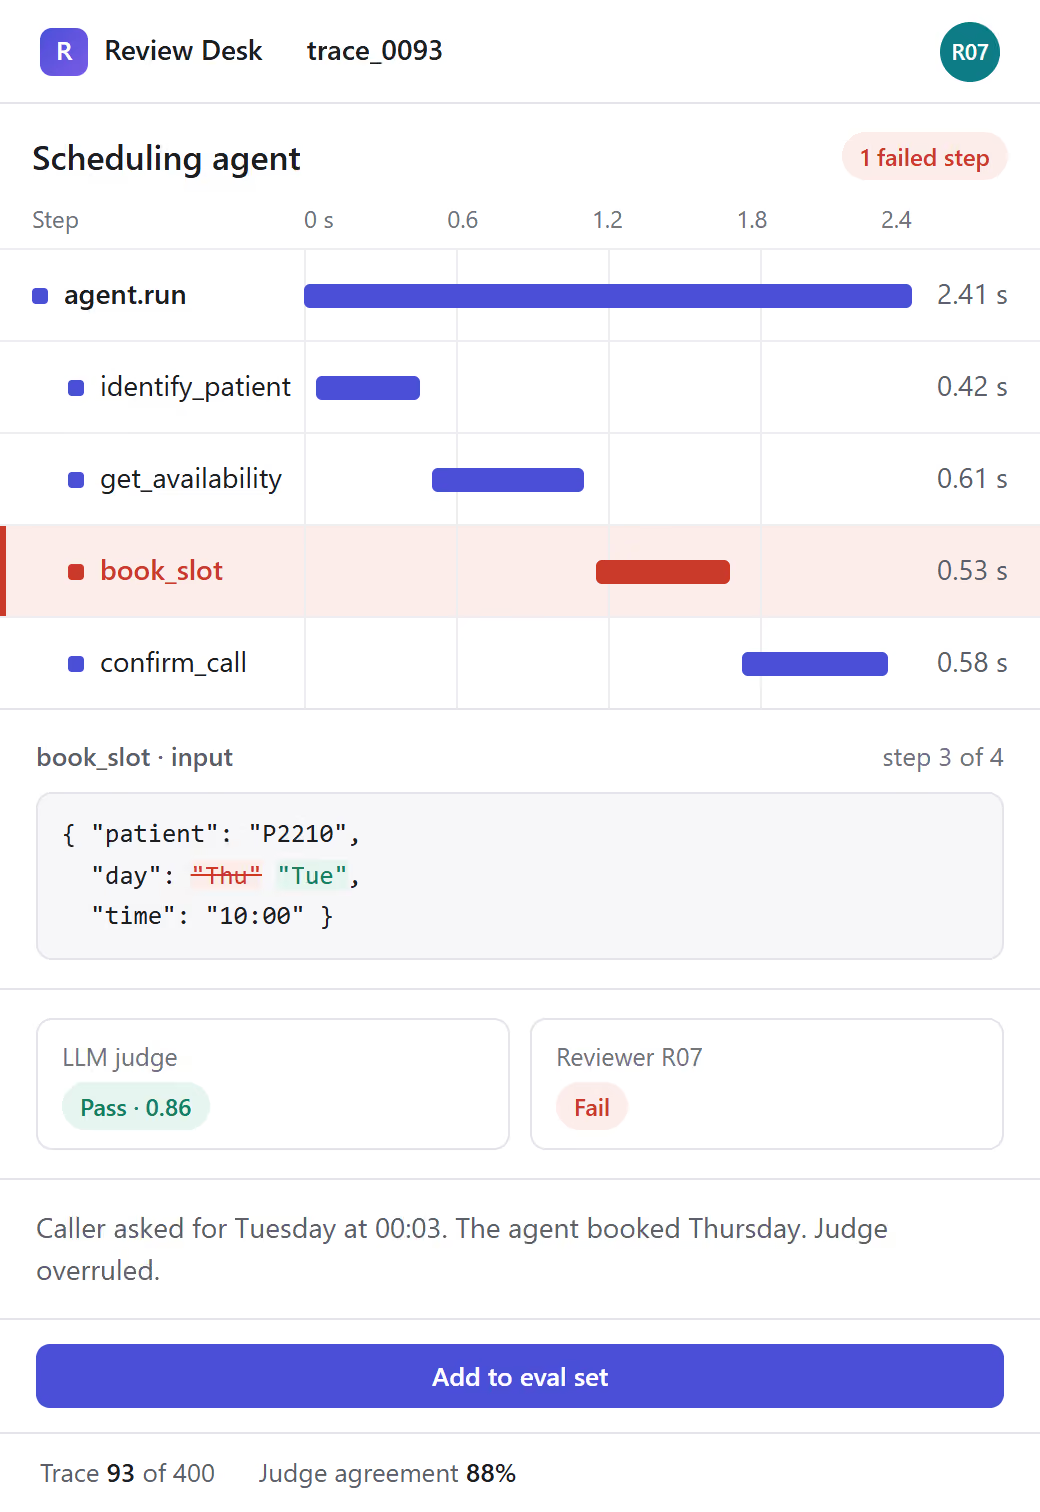
Humans in your production loop
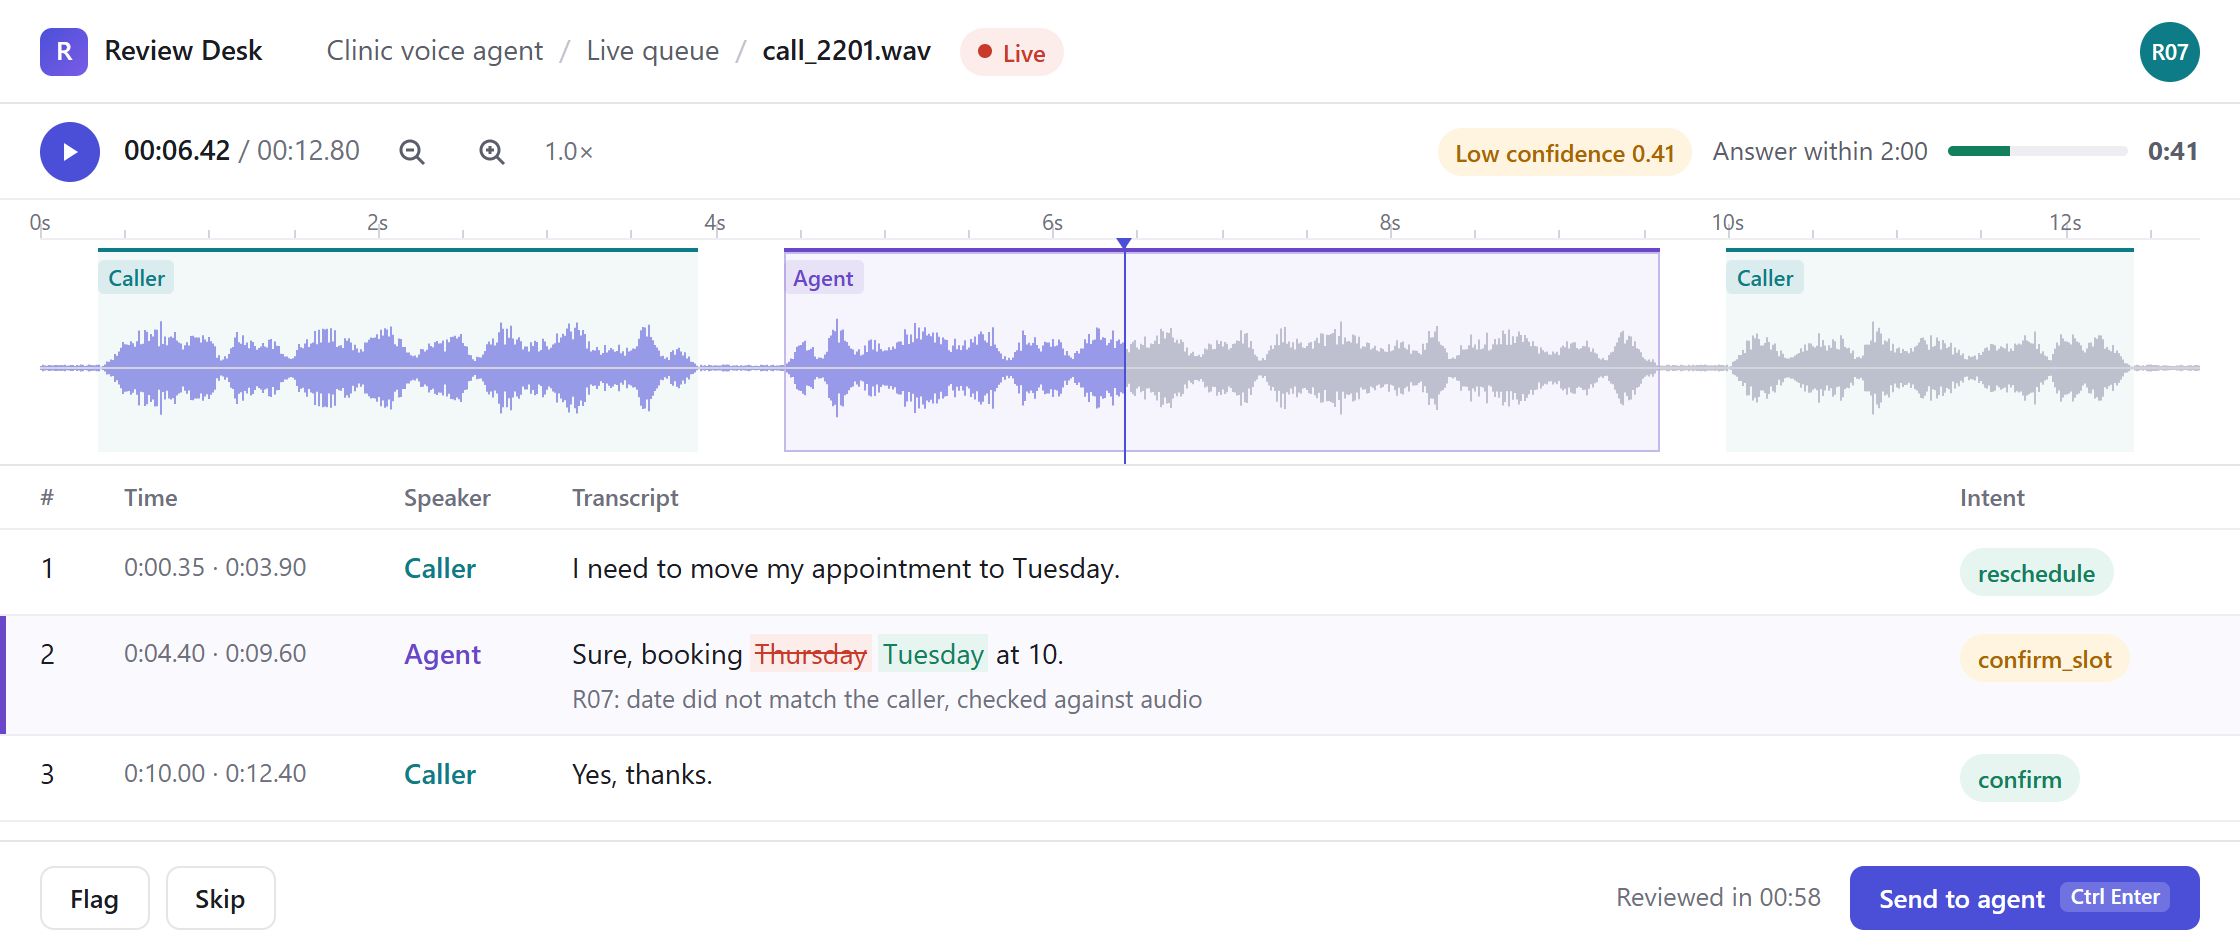
Low confidence output routes to a reviewer in under 2 minutes, 24/7. Every correction comes back as training data.
Live review services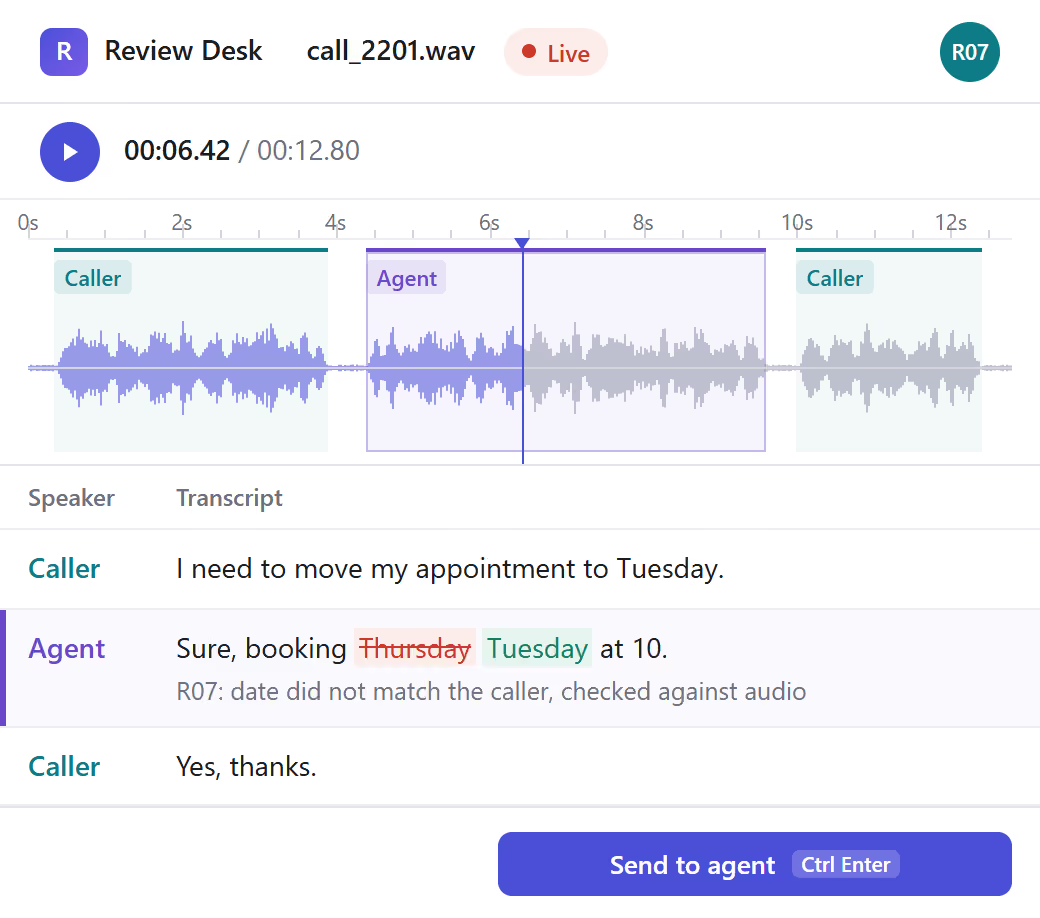
Pipelines around your data
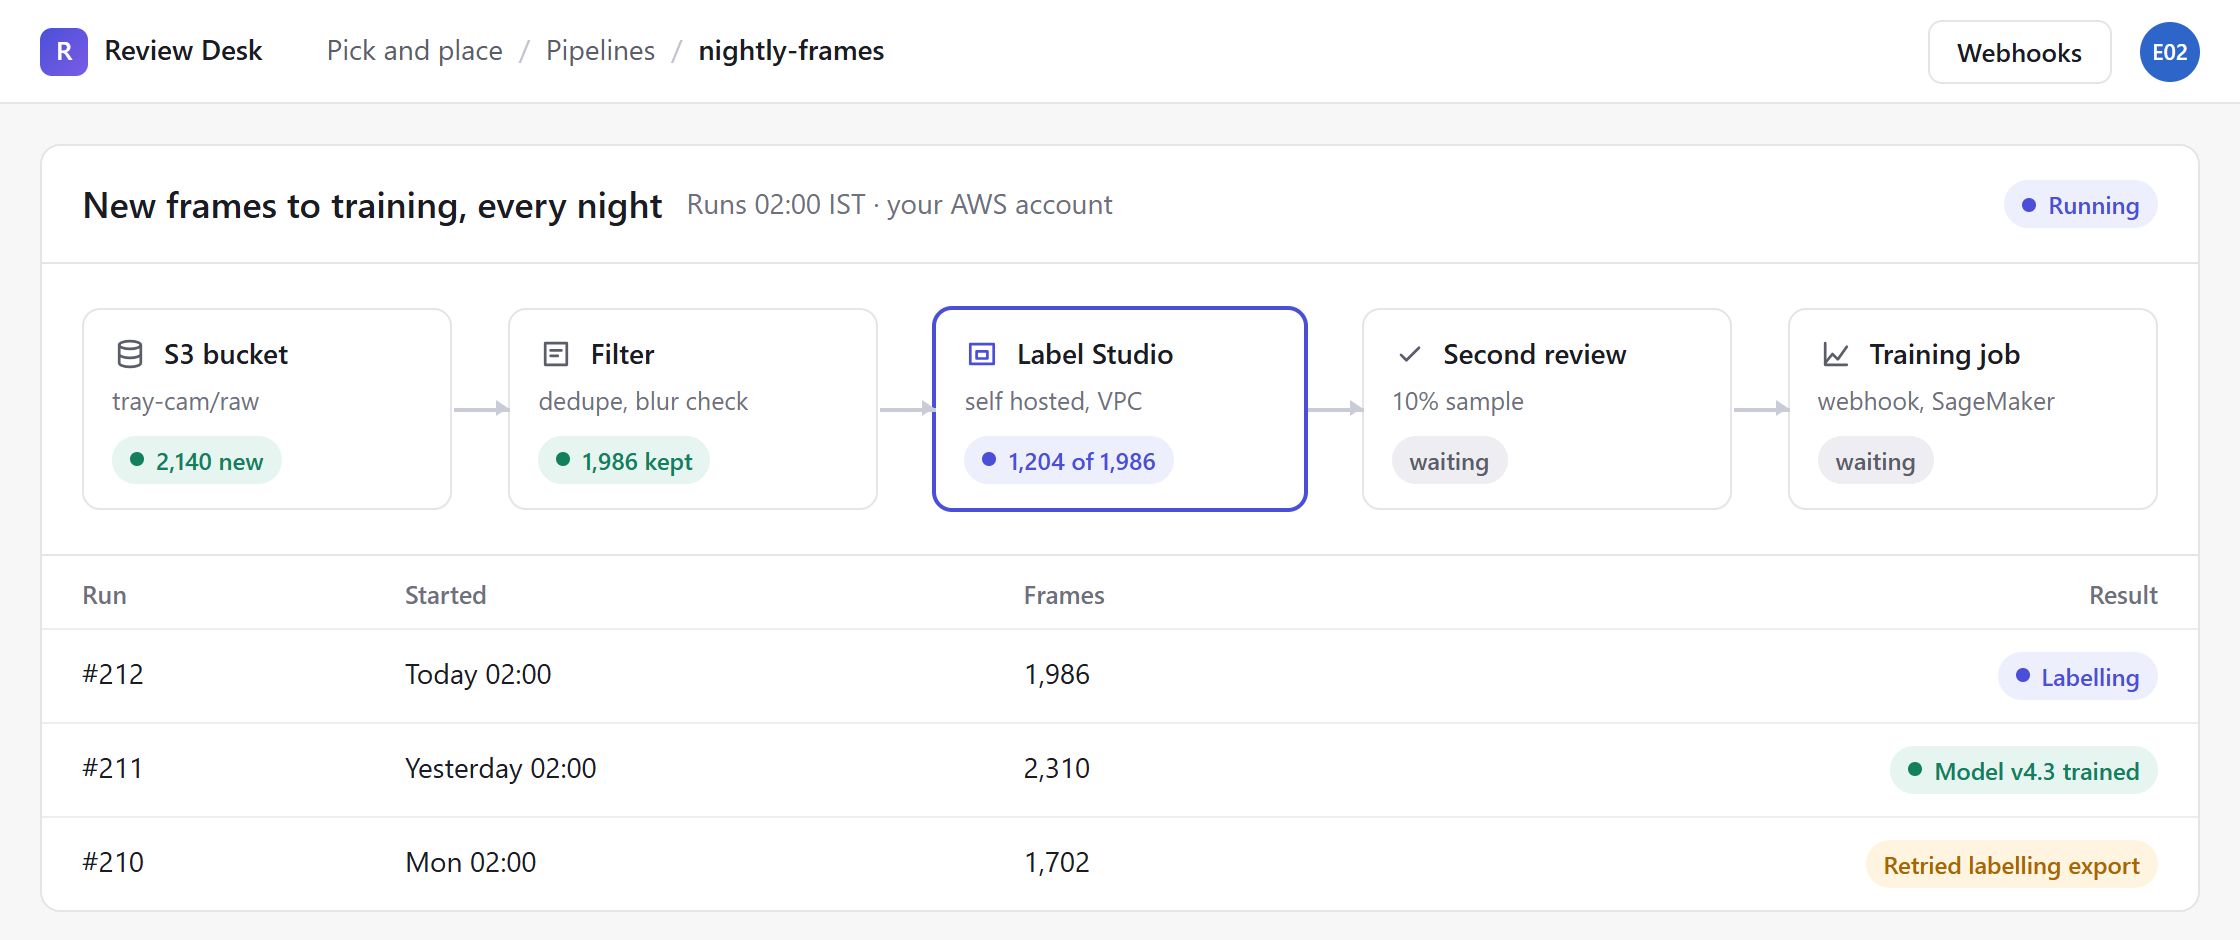
Labelling tools set up in your cloud, and pipelines that move new data to labelling, review and training without anyone copying files.
Engineering services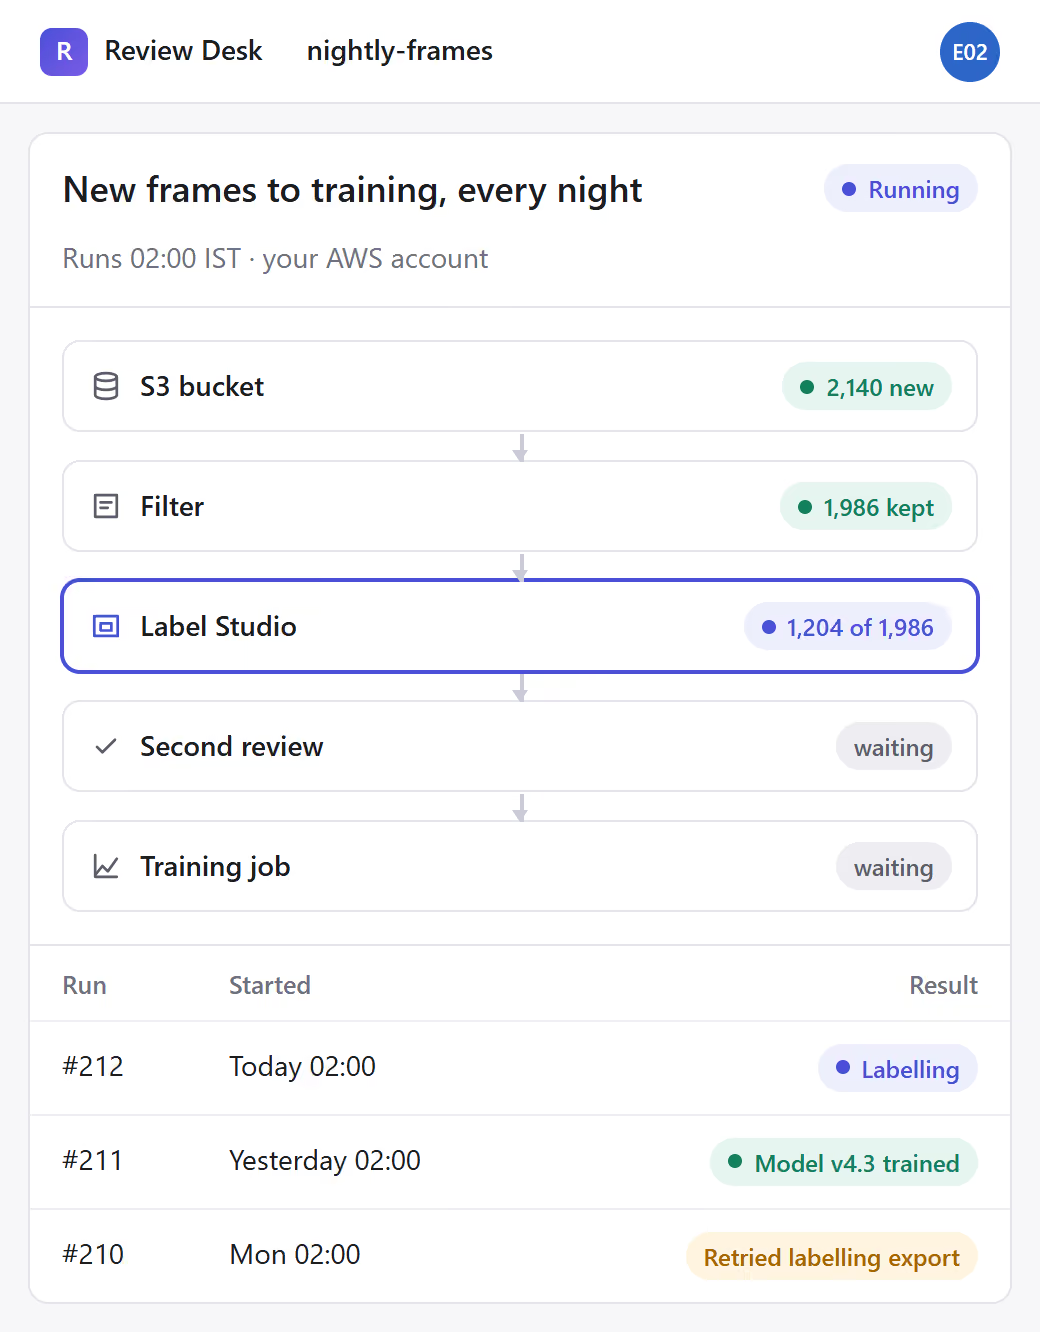
The right reviewer for the subject
Clinicians, engineers and linguists for work a generalist would get wrong, recruited and vetted through Rubricate.
Expert network services
Tell us what you are building.
Six kinds of AI, each with the data, tools and failure modes it needs.
Vision & Physical AI
Robots, vehicles, vessels and inspection models trained on data a person has checked, then watched in production.
- Robotics and manipulation
- Autonomous driving and LiDAR
- Inspection and defects
- Video and event tagging
Dataimage · video · LiDAR · point cloud · thermal
ProofClient B · Client C · Client E · Client F
See Vision & Physical AI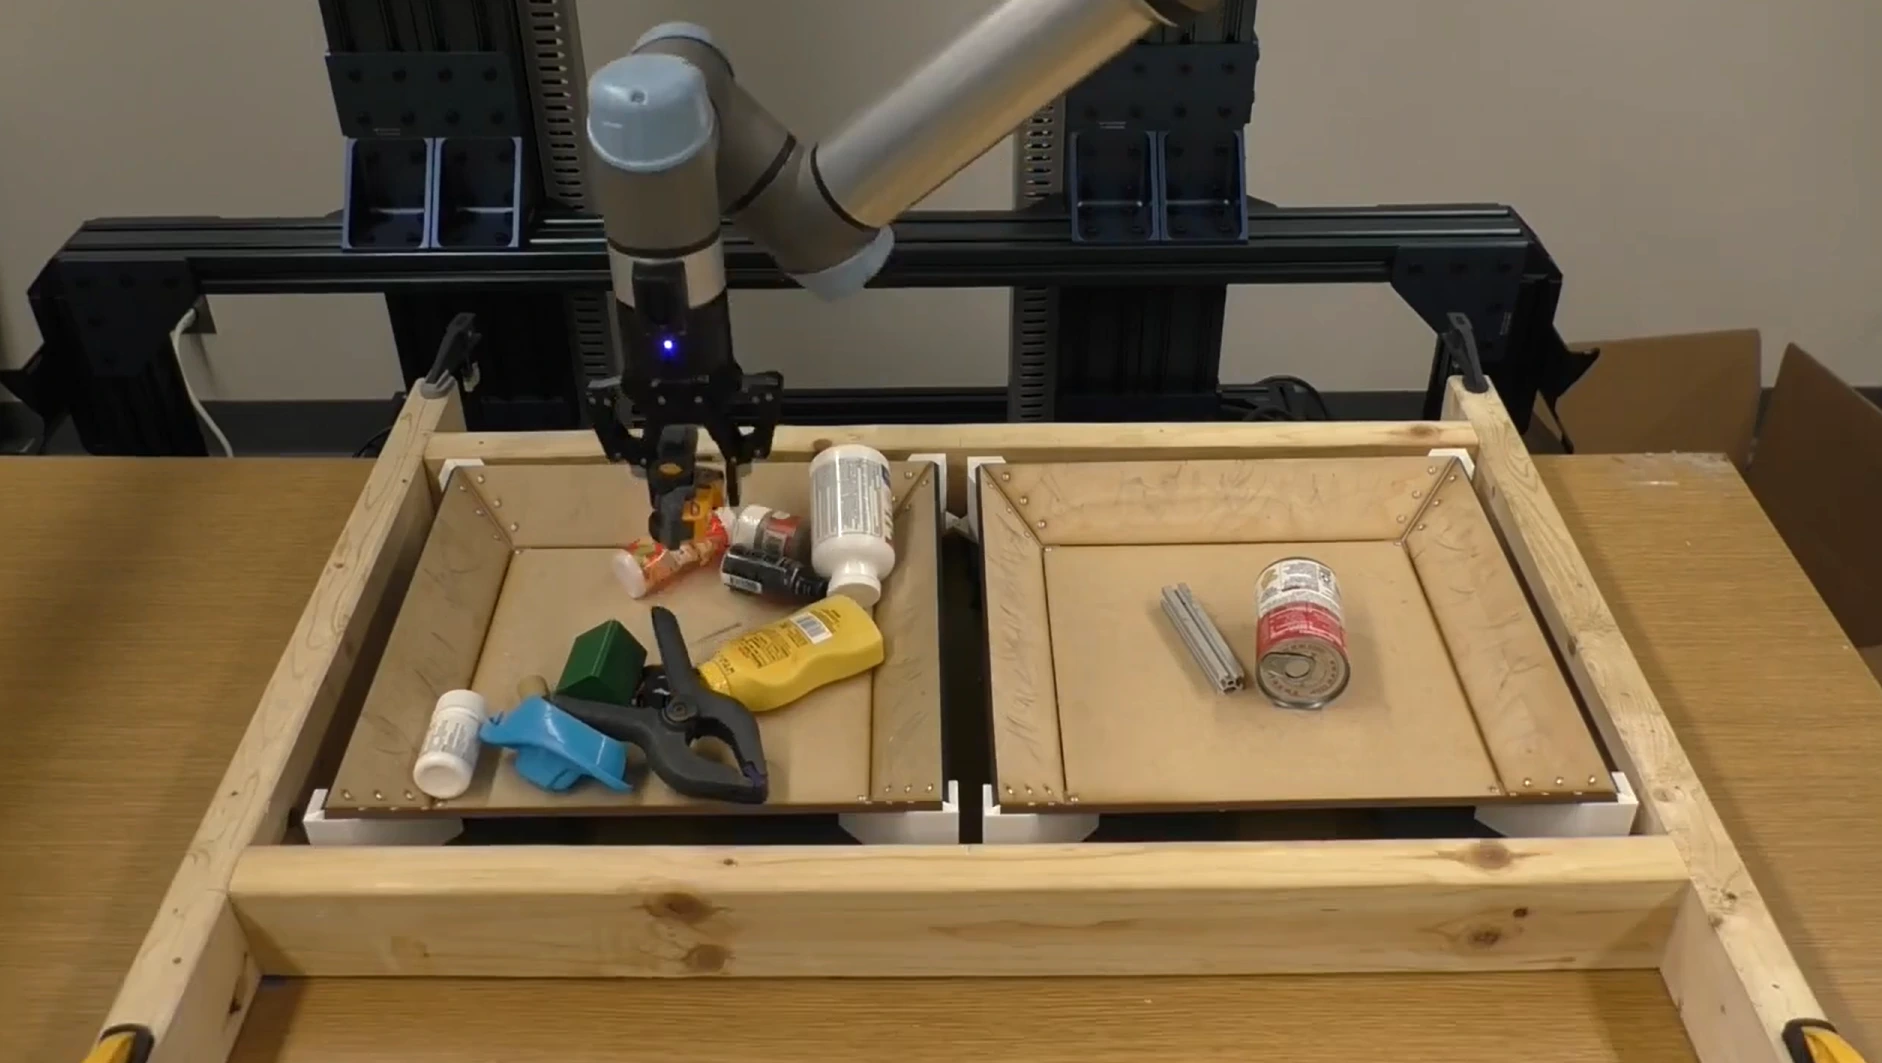
Documents & Drawings
Invoices, forms and technical drawings read field by field and symbol by symbol: construction sets, mechanical parts, electrical schematics and P&IDs.
- Invoices and forms
- OCR and field extraction
- Construction takeoff
- Mechanical and electrical drawings
Datascans · PDFs · drawings · handwriting
ProofClient A · Client J · Client K · Client L · Client I · 1,500+ symbol classes
See Documents & DrawingsVoice & Audio
Transcripts, speaker turns and intent labels checked against the audio, and voice agents reviewed call by call.
- Transcription
- Speaker diarization
- Voice agent review
- Indian languages
Datacalls · speech · English and Indian languages
ProofHealthcare voice agent company, 10 checks per call
See Voice & AudioGenerative AI
Preference data, fine tuning data, red teaming and evaluation for language, image and video models.
- RLHF and preference data
- SFT data
- Red teaming
- RAG and grounding evaluation
- Image and video generation evaluation
Dataprompts · answers · generated images · generated video
ProofDomain experts recruited through Rubricate
See Generative AI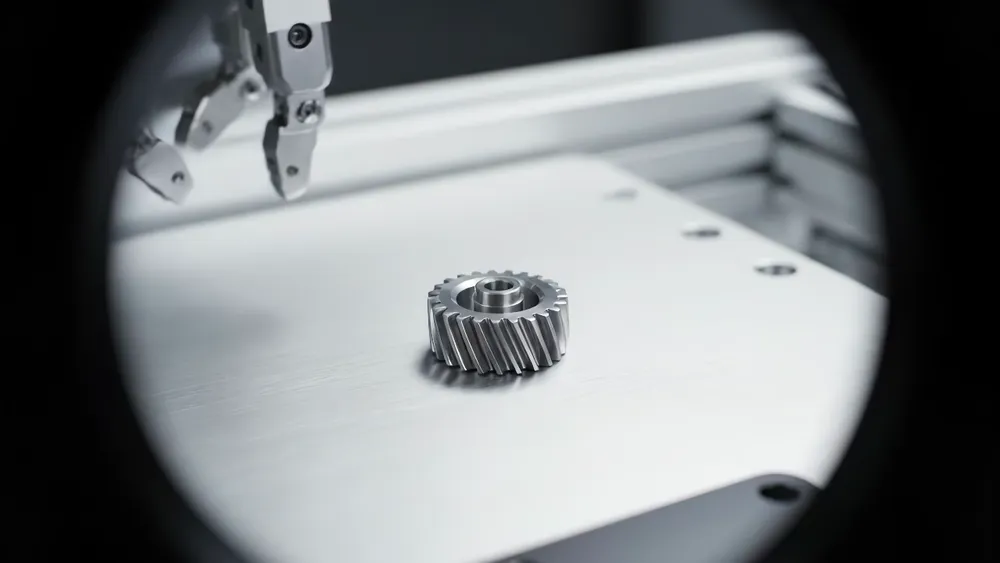
AI Agents
Agent traces reviewed step by step, with the first failing step tagged and your automated judge checked by people.
- Trace review
- LLM judge checks
- Tool call evaluation
Datatraces · tool calls · conversations
ProofAgent and LLM judge checked by a person, call by call
See AI AgentsContent moderation & safety
User content labelled against your policy, live queues reviewed by people, and model output checked for safety.
- User content and NSFW
- Policy labelling
- Live moderation queues
- AI output safety review
Dataimages · video · live streams · text · comments
Proof[REAL DATA: client and volume]
See Content moderation & safety
One piece of data, followed from raw file to production.
Most data work breaks at the handoff between stages. We run every stage on one schema and one quality record, from the first batch to live traffic, for every kind of data.
precision 0.94 · recall 0.91
blue buses read as trucks
corrected to bus in 01:38
added to retraining set
00:03 i need to see doctor men on again thursday morning if possible
00:03 Caller I need to see Dr. Menon again, Tuesday morning if possible.
00:03 I need to see Dr. Men on Menon again, Thursday Tuesday morning if possible.
word errors 6.1% · names and days worst
"Tuesday" heard as "Thursday"
00:16 Agent You're booked for Thursday Tuesday at 10 AM.
corrected to Tuesday in 00:52
added to retraining set
Prompt · Summarise this discharge note for the patient.
You were treated for a chest infection. Take amoxicillin three times a day for 5 more days. Your doctor stopped naproxen. Keep using your inhalers as before.
Prompt · Summarise this discharge note for the patient.
You were treated for a chest infection. Take amoxicillin three times a day for 5 more days. Your doctor stopped naproxen. Keep using your inhalers as before.
Prompt · Summarise this discharge note for the patient.
You were treated for a chest infection. Take amoxicillin three times a day for 5 more days. Your doctor stopped naproxen. Keep using your inhalers as before.
agreement between reviewers 91%
reason for stopping a drug often missing
Sampled from live traffic
You were treated for a chest infection. Take amoxicillin three times a day for 5 more days. Your doctor stopped naproxen because it can upset your stomach. Keep using your inhalers as before.
fixed and approved in 02:10
added to the preference set
- agent.run
- identify_patient
- get_availability
- book_slot
- confirm_call
- agent.runrun
- identify_patientverify identity
- get_availabilitylook up slots
- book_slotbook
- confirm_callread back
- agent.run
- identify_patientpass
- get_availabilitypass
- book_slotfail · wrong day
- confirm_callfail
reviewer failed it at step 3
judge only checks the read back
- agent.run
- identify_patientpass
- get_availabilitypass
- book_slotfixed · Tuesday
- confirm_callpass
rebooked for Tuesday in 01:12
rule added to the rubric
- collect
Collect
We source and capture what your model is missing: rare classes, new geographies, speakers in the languages your users speak, and prompts your model has never seen.
How we collect data - annotate
Annotate
Boxes, polygons, keypoints, transcripts, speaker turns, claims and agent steps, built to your schema in your tool or ours.
- Independent reviewers, never the labeler checking their own work
- Every label logged with annotator ID and timestamp
- COCO, YOLO, JSONL or your own format
- evaluate & align
Evaluate & align
Scored comparisons against ground truth, rubric scoring, preference ranking, red teaming and agent trace review, so you know where the model fails before your users do.
Evaluation services - live review
Live review in production
Low confidence predictions and sampled outputs route to a person in under 2 minutes, 24 hours a day. Every correction comes back to you as training data.
- Three shifts, weekends and public holidays covered
- Plugs in by API, webhook, Slack or your own queue
- 24/7 live operations since [REAL DATA: year]
Bring us the data your model gets wrong.
Send a small batch and get it back done, free, usually within 24 to 48 hours. You judge the work before you pay for anything.