Text
Chat assistants, RAG systems, agents, summarisers, classifiers and extraction models
What we look for
- Claims the sources do not support
- Wrong or missing citations
- Instructions not followed
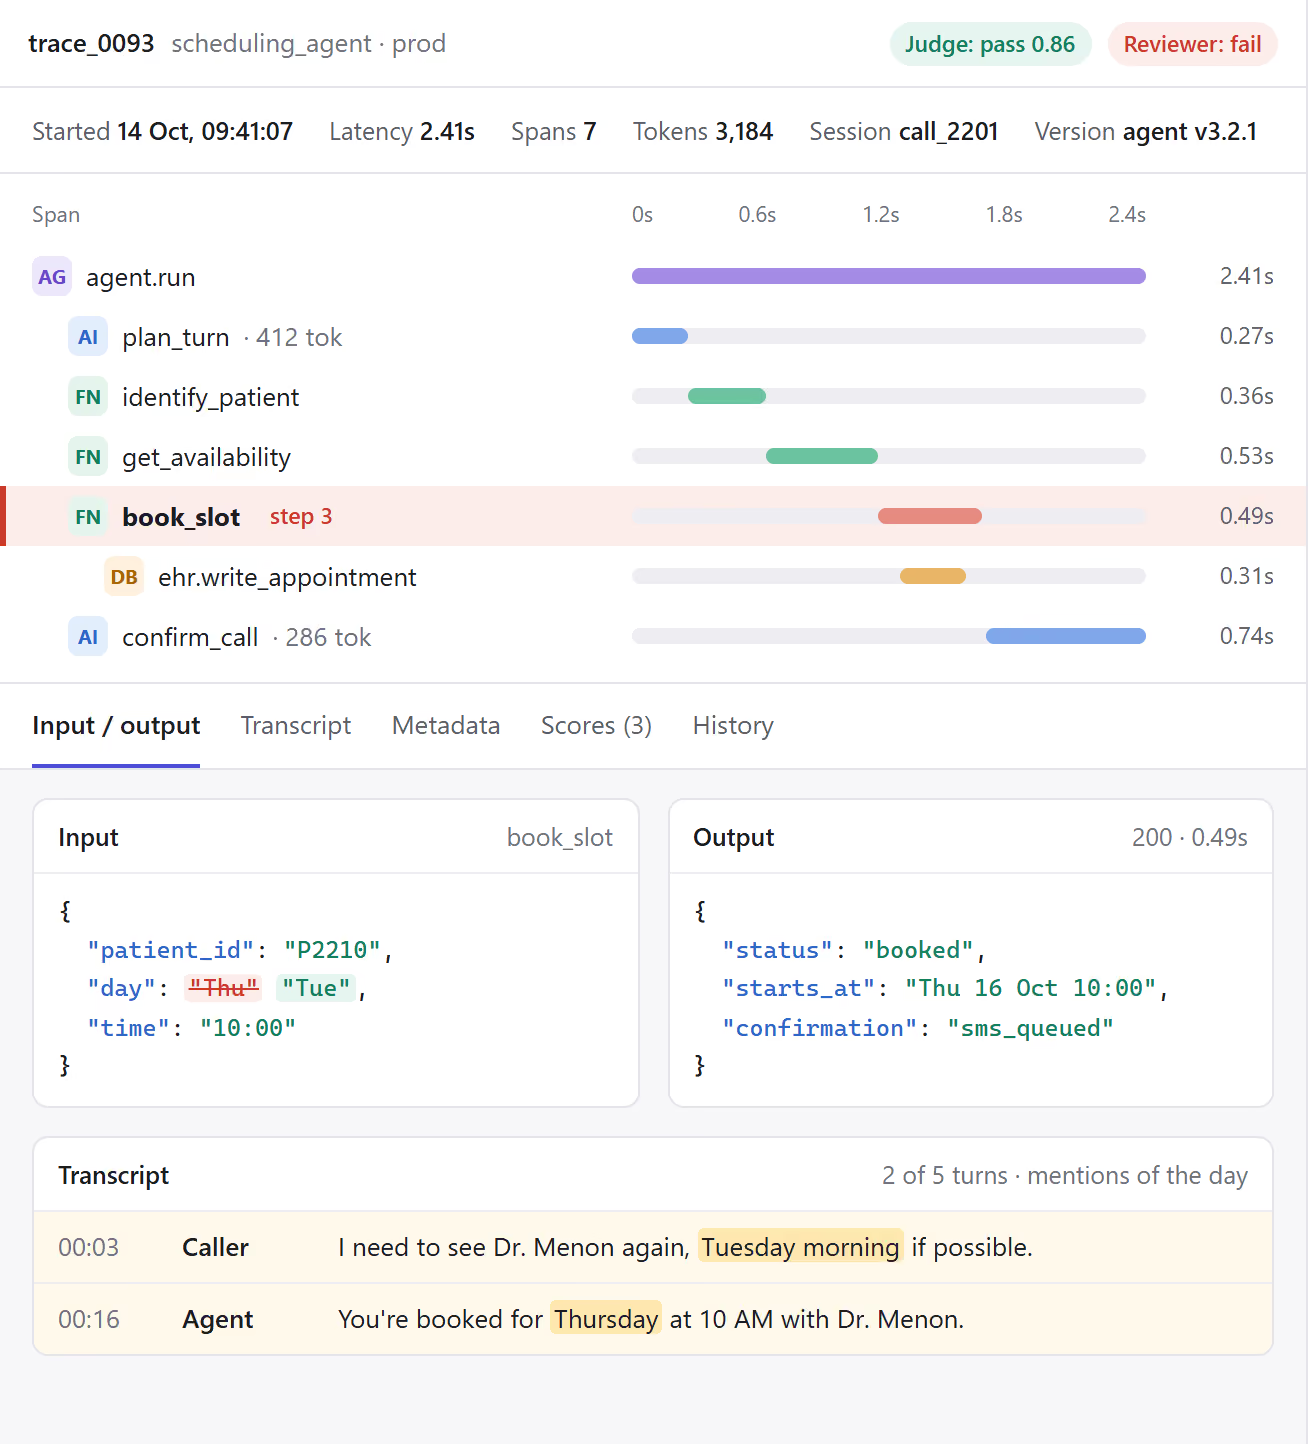
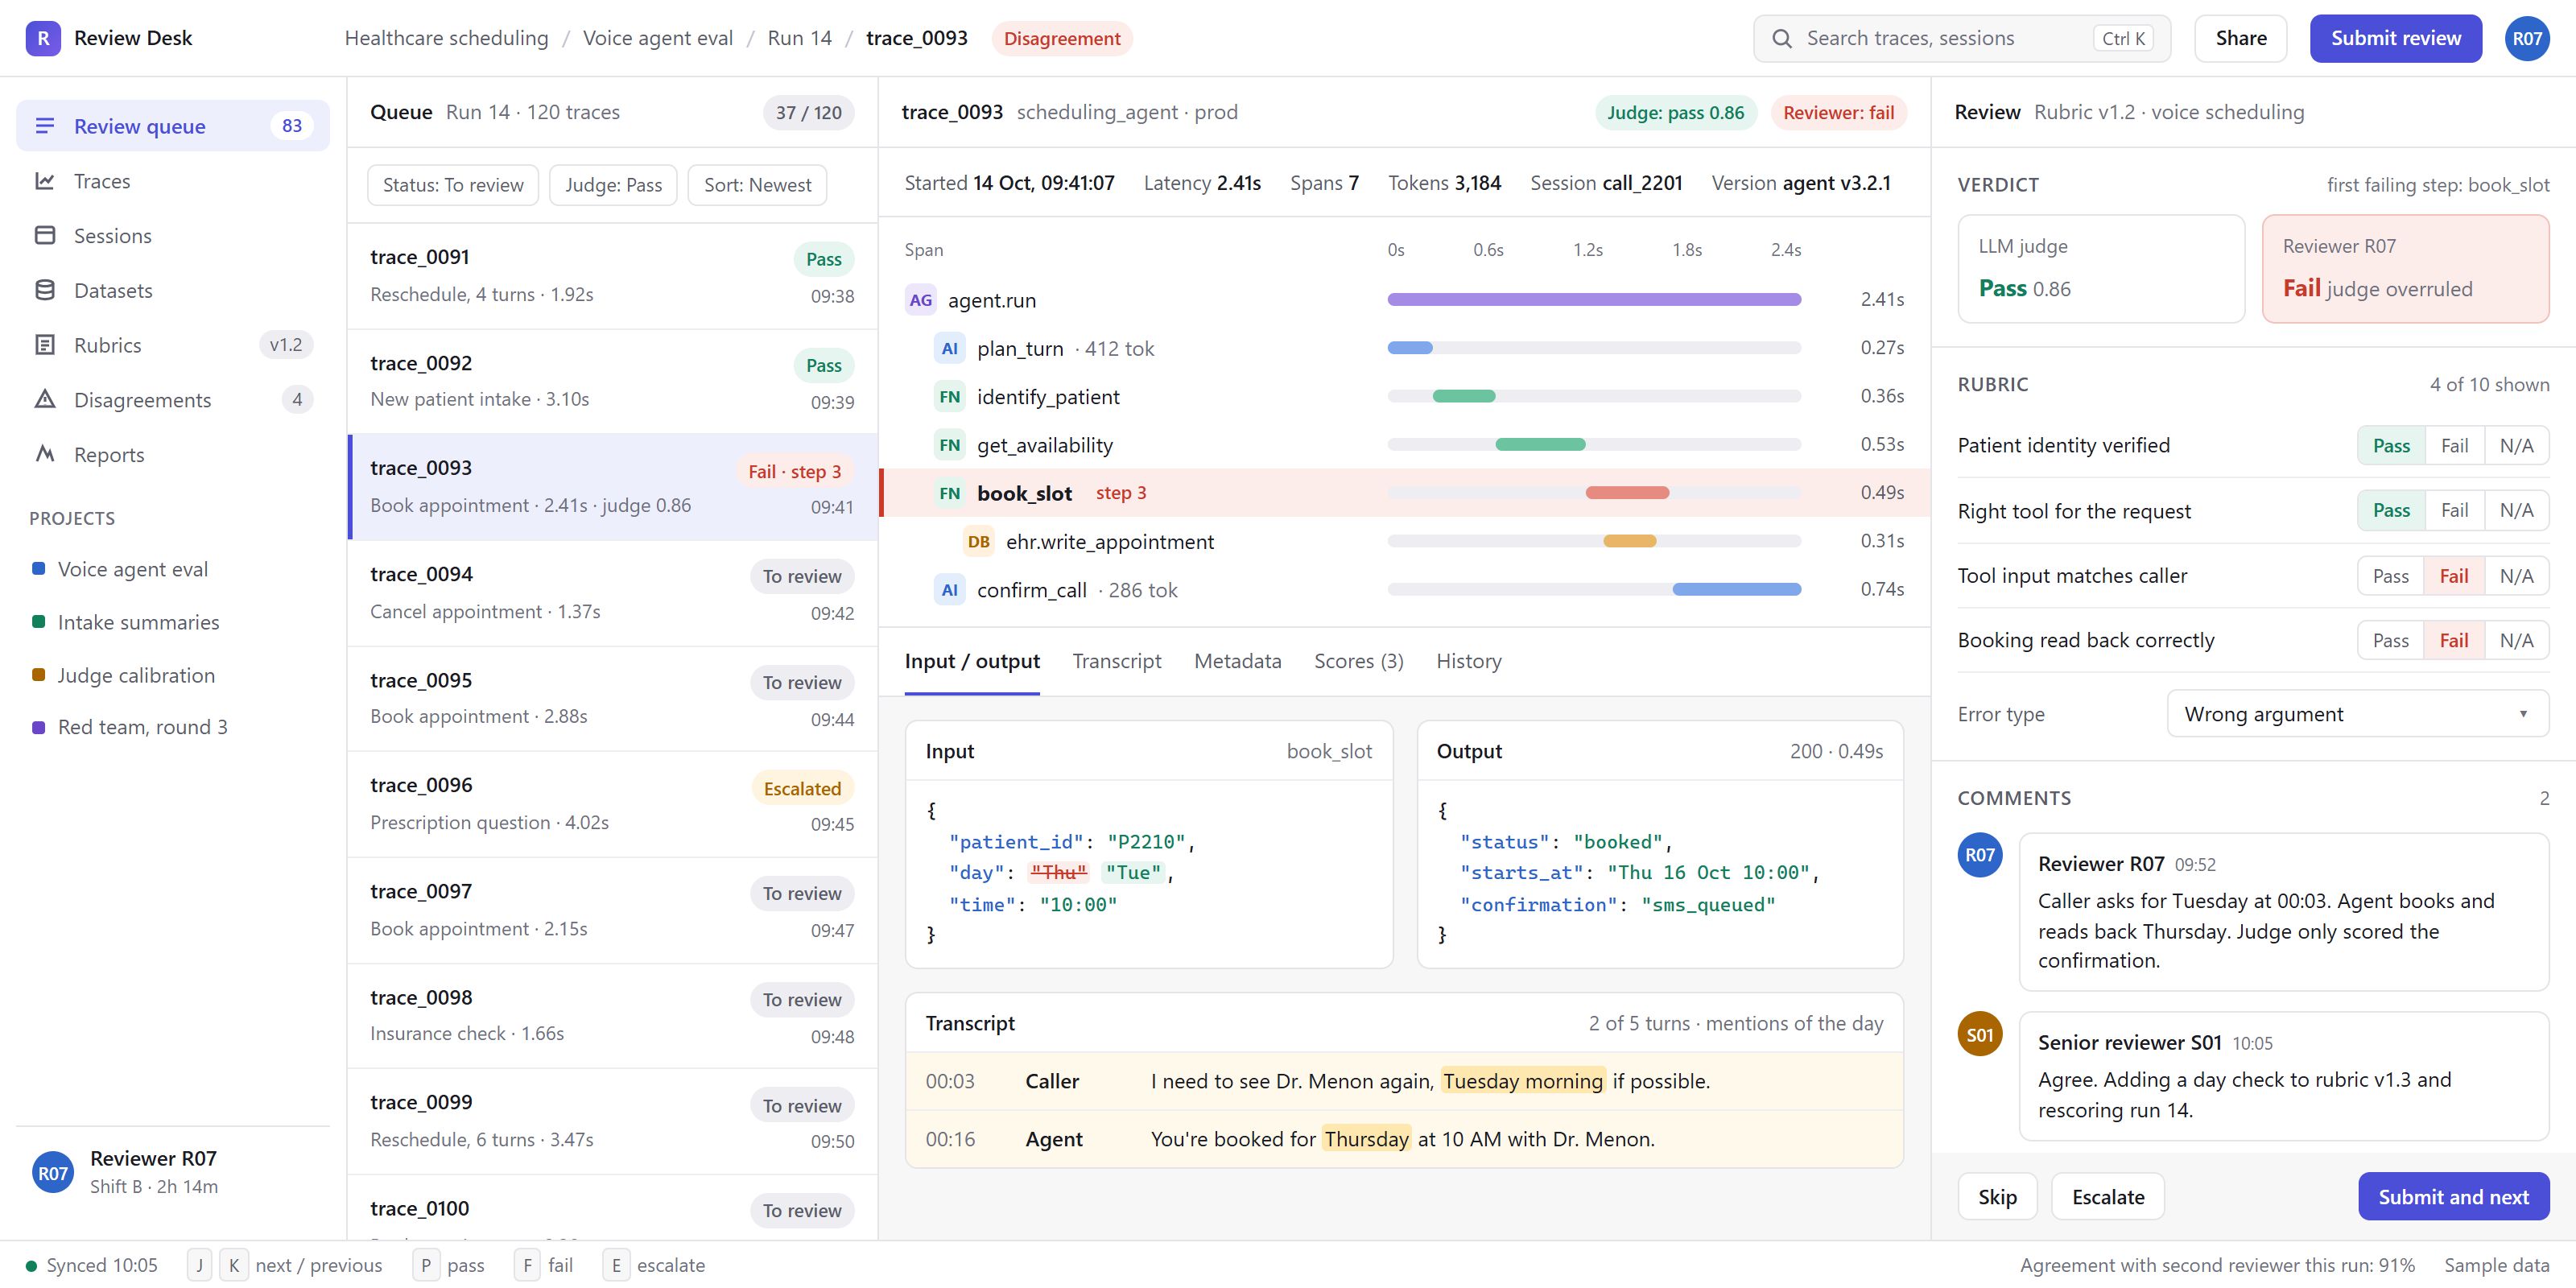
- Wrong tool or wrong arguments in agent runs
- Unsafe, biased or over cautious answers
What you get
- Pass rate per rubric criterion
- First failing step in agent runs
- Preference rates with reasons